AI tools for product descriptions are worth evaluating not by a single impressive piece of copy, but by the stability of results across the whole catalogue. In e-commerce, what matters is rapidly rolling out thousands of SKUs without losing consistency, facts or usefulness for the customer. Repeatable quality matters more than the occasional excellent description, because it is what determines the scale, control and profitability of the process. In practice, the outcome is decided by the quality standard, the source data and the way the tool turns it into ready-to-publish copy.
What does repeatable quality in product content mean?
Repeatable content quality for products means that the system generates descriptions according to a consistent, defined standard. That standard covers factual accuracy, completeness of data, brand tone, structure and uniqueness within a given category. The point is not identical descriptions, but a predictable level of quality across many similar SKUs. This means the team knows what to expect before publication and can more easily spot deviations.
In practice, good product copy should answer the user’s transactional and informational intent. It should show features and benefits, uses, important differences and the customer’s basic answers to questions. If a tool does this well one time and superficially the next, it does not deliver repeatable quality. Such instability slows publication and increases the risk of thin content.
That is why the tool should be tested on a batch of products from one category, not on a single example. Only a series of results shows whether it maintains tone, a complete structure and avoids internal duplication. This is especially important when the catalogue is large and the descriptions are meant to support both SEO and the use of content by AI systems.
How do source data affect the quality of generated content?
Source data affect the quality of generated content directly, because the model works with what it receives from the PIM or feed. If the input is incomplete, the output will be generic, imprecise or incorrect. Missing attributes, variants or uses usually end in important information being omitted. This is the classic GIGO principle: bad data produce a bad description.
In practice, the most important data are those that describe the product unambiguously and can be mapped to a template. These are most often:
- attributes and technical specifications,
- size, colour or capacity variants,
- materials, composition and finish,
- uses, compatibility and usage limitations.
When these fields are structured, the tool can correctly build consistent descriptions across the whole category. When they are entered chaotically or only partially, the model starts guessing or oversimplifying. Then the number of rejections in quality control rises, as does the need for more manual editing.
If the catalogue has gaps, it is worth enriching it with additional information before generation. This is helped by synthesising benefits from parameters, analysis of customer reviews and adding features that answer real shopper questions. Such enrichment raises the usefulness of the content, but should not replace official product data.
Data enrichment as a key process in creating product descriptions
Data enrichment is a key process because it turns raw parameters into information that is useful for the customer and the model. As a result, the description does not stop at a list of technical features, but also shows usage, benefits and limitations. This is especially important where the feed contains only shortened field names or incomplete specifications. Well-enriched data reduce the risk of the model guessing and clearly improve the stability of results.
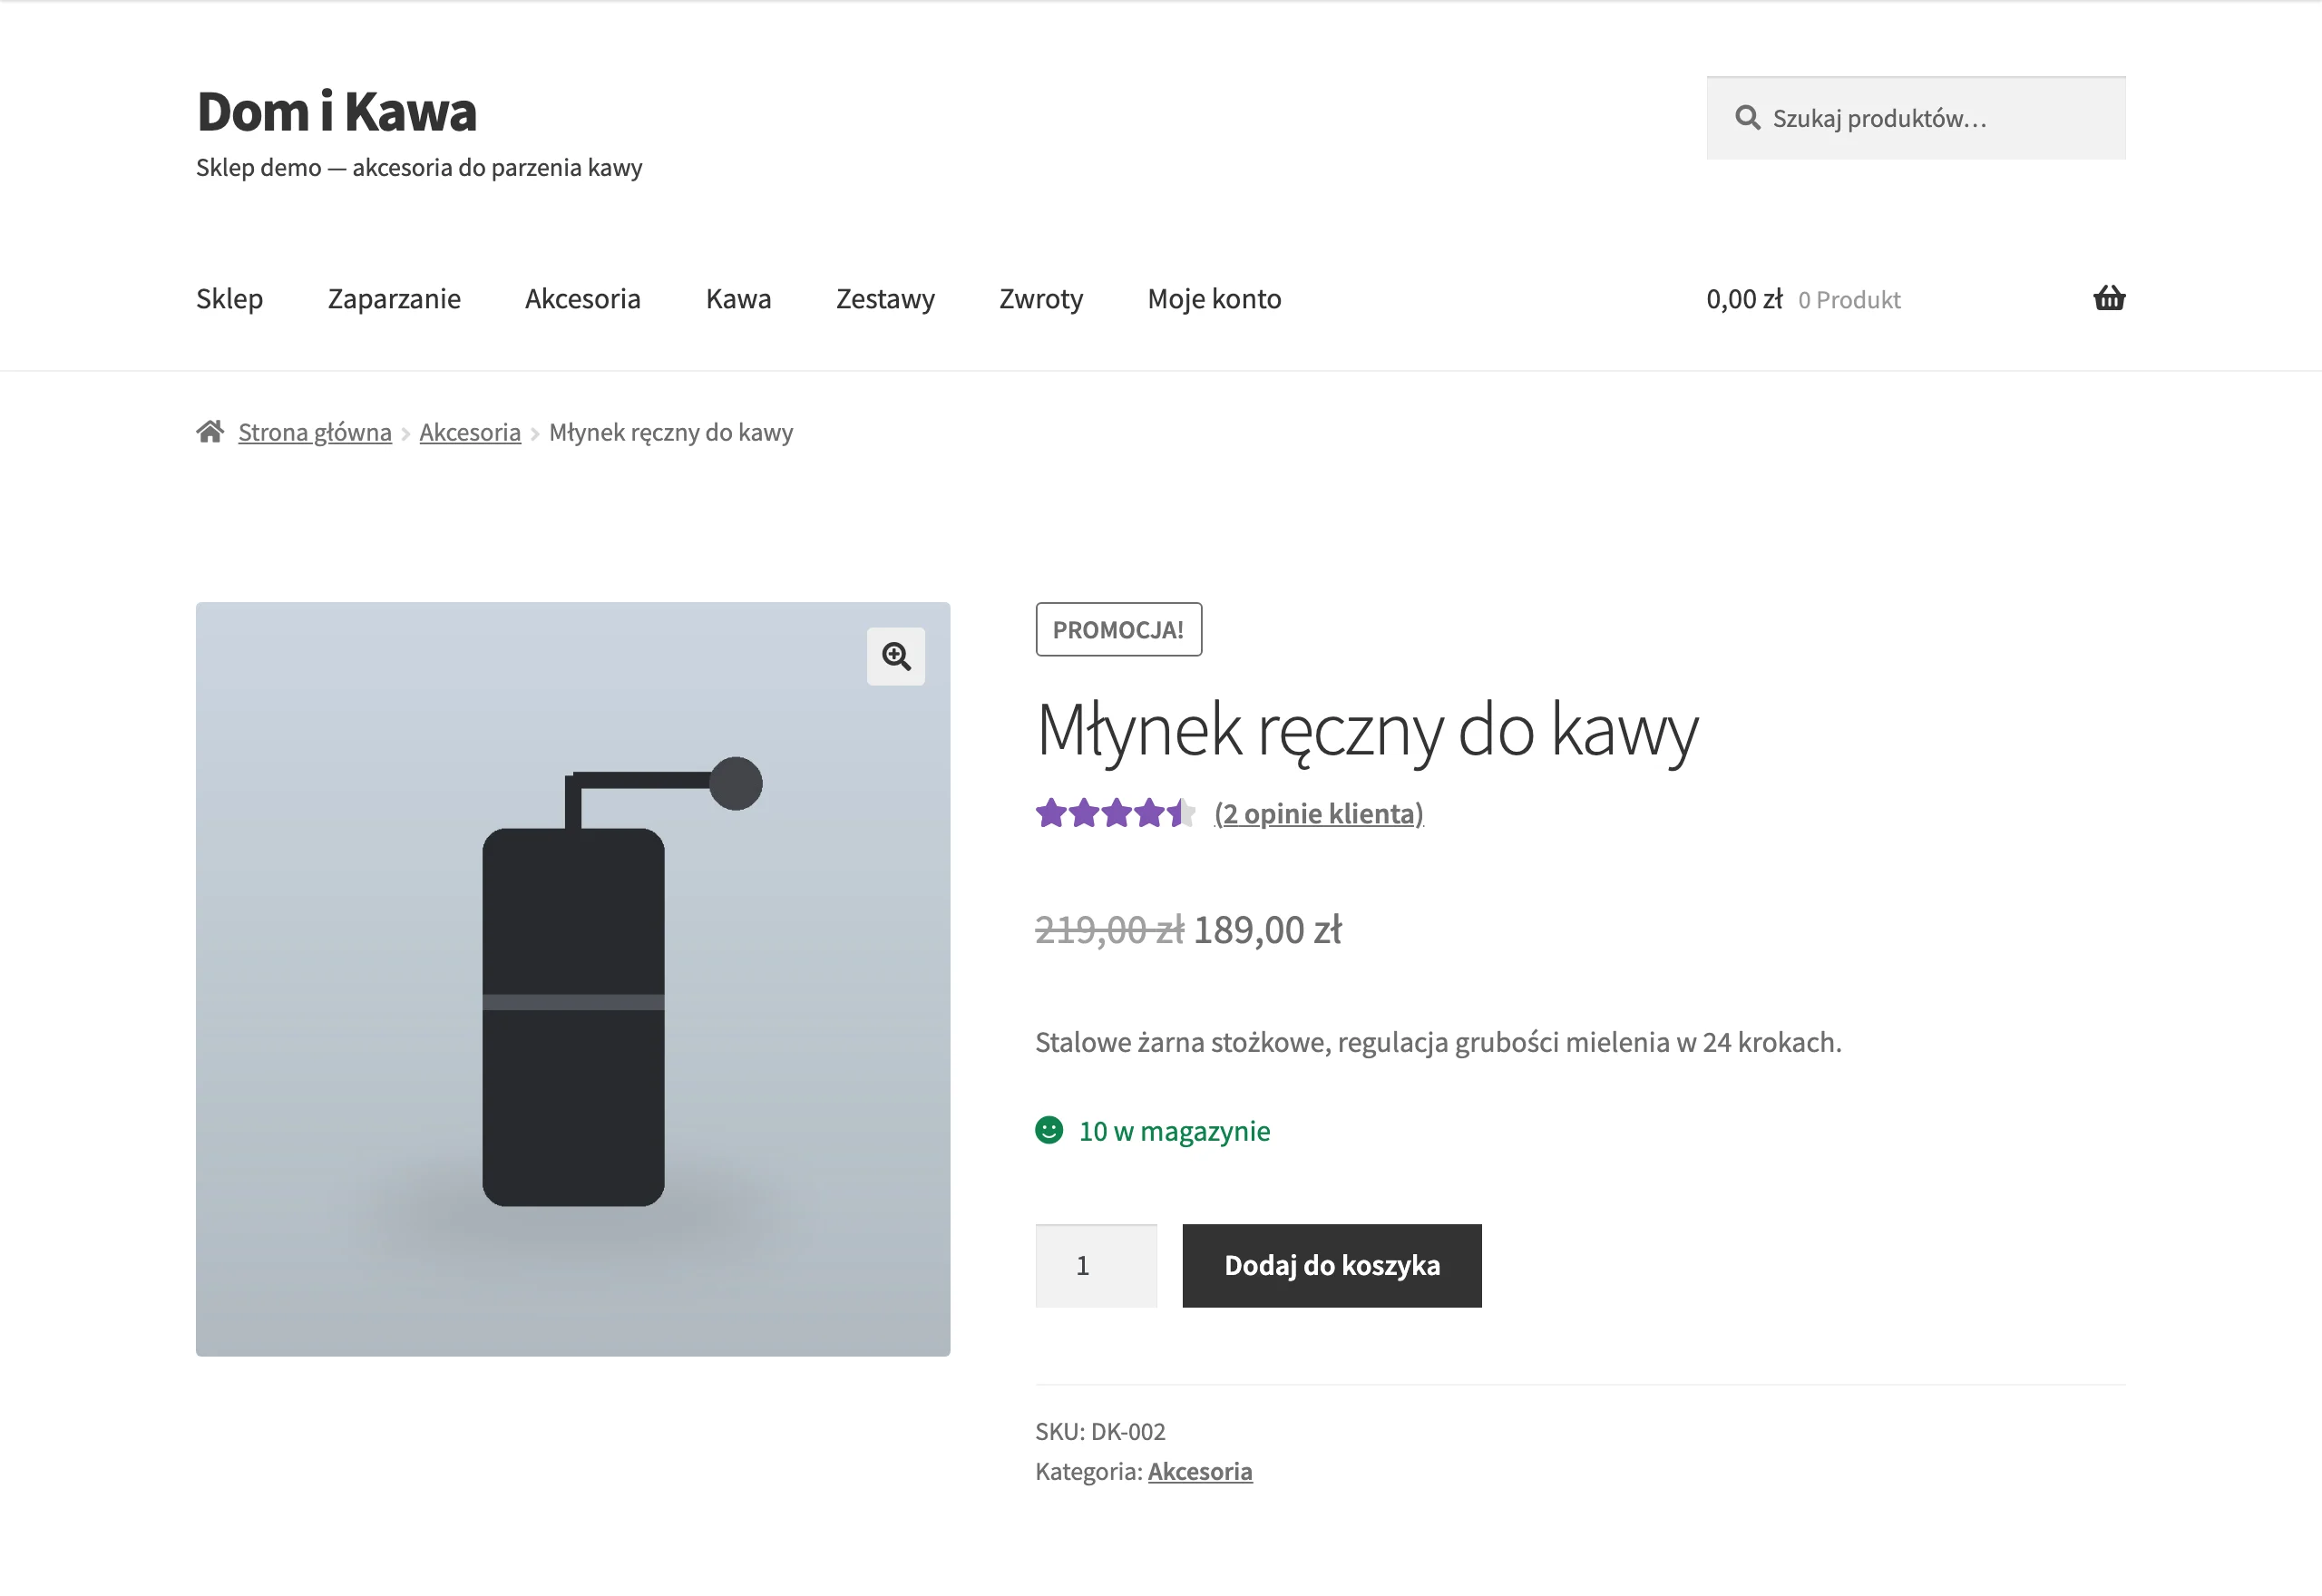
In practice, enrichment can take several forms. One is extracting visible features from images, for example the type of fastening, finish or arrangement of elements. Another is synthesising benefits from technical parameters, when the system translates data into real product use. Customer review analysis can also be useful, because it shows the questions that are worth covering in the copy.
This stage must be handled carefully, because not every additional interpretation is safe. Information derived from reviews or images should support the description, not replace official product data. The best approach is to separate confirmed fields from inferred fields and subject them to separate validation. This reduces factual errors and makes the later QA stage easier.
The role of prompt engineering in achieving consistent content quality
Prompt engineering determines whether the same data produce descriptions that are consistent, complete and aligned with the brand tone. A language model on its own will not establish the correct structure or content priorities if it is not given clear instructions. The prompt should define the text’s purpose, required sections, style, length and the rules for using input data. The more precise the instruction, the less randomness in the result.
A good prompt does not stop at one sentence. It should include variables mapped from product attributes, the required elements of the description and examples of a correct result in a given category. Few-shot helps maintain format and tone, especially with large SKU volumes. This has practical value, because it shortens manual editing and reduces the proportion of content rejected in quality control.
The most common mistake is using one universal prompt for the entire catalogue. Products differ in attributes, usage and the scope of customer questions, so they need separate rules. Otherwise, the description will be either too generic or overloaded with irrelevant information. Repeatable quality appears when the prompt is designed for a specific category and tested on a series of similar products.
How to choose the right AI tool for generating product content?
The right AI tool is one that delivers a predictable output for an entire product category, not just for one example. In practice, the most important thing is mapping product attributes to variables in prompt templates. If the system cannot work with data from the PIM or feed, gaps, generalities and errors will quickly appear. This is precisely the stage at which it is easiest to distinguish a demo tool from a production tool.
A good solution should allow you to create separate templates for product segments and version their changes. This is important because a category with simple accessories needs different rules than technical or variant products. Just as important is integration via API and batch mode, because without them scale means manual operations. If the tool does not support templates per category, repeatable quality usually ends at the pilot stage.
When choosing, you also need to assess the language model, support for Polish and the cost of generating a single description. The model affects language quality, the ability to follow instructions and data security at the same time. It is worth checking whether you can change the model or adapt it to your own needs if costs or requirements change. Separately, you should verify the privacy rules and the way product data is sent to the API, because this affects operational risk.
The most practical selection method is to test on one coherent product category. Such a test should cover not only text quality, but also the correction rate, data consistency and ease of QA implementation. Only then can you see whether the tool really shortens publishing time and maintains standards with a larger number of SKU. A nice style alone is not enough if the team has to manually correct structure, facts and brand tone.
Managing the content generation workflow and its impact on scalability
Scalability comes from a workflow that moves a product from source data to publication without manual chaos and without losing quality control. In practice, this is not about the text generation alone, but about the entire operational chain. When this process is fragmented and inconsistent, the number of SKU grows faster than the team’s ability to verify them. Then automation stops saving time and starts creating backlogs.
The most useful workflow includes stable stages that can be measured and improved:
- enriching product data,
- mapping data to a prompt template,
- generation via API or in batch mode,
- automatic QA validation,
- human verification when needed,
- publication, monitoring and content refresh.
This sequence matters in practice because each stage reduces a different type of error. Automatic validation catches inconsistencies with data, duplication and prohibited phrasing. Human-in-the-loop safeguards brand tone, facts and situations that the rules did not anticipate. Publishing without these filters may speed up the launch, but usually increases the cost of later corrections.
The scope of automation should depend on the value and complexity of the product. For simple, low-margin SKU, fuller automation can be used if the data is complete and QA works properly. For strategic, regulated or complex products, a human approval stage is mandatory. This does not slow the process down for no reason; it protects against costly mistakes where the risk is highest.
A well-managed workflow also makes it possible to control cost at the level of the entire catalogue. Cost is affected by the LLM model, prompt length, response length and the amount of manual work. If the team does not measure cost per description, time to publication and the rejection rate in QA, it is difficult to assess the profitability of automation. In practice, scaling works only when quality, time and cost are monitored simultaneously.
The most common risks and mistakes in product content automation
The most common risks in product content automation are fact hallucinations, loss of brand tone and publishing descriptions based on incomplete data. In practice, the problem usually starts earlier than at the generation stage itself. The model starts guessing when it receives gaps in attributes, a poorly chosen template or too broad a prompt. The result is descriptions that are linguistically correct, but unreliable in substance and weak for sales.
A particularly common mistake is using one prompt for the entire catalogue. This shortcut reduces relevance because different information is crucial for electronics and different information for clothing or accessories. Equally problematic is the lack of automatic QA, because then duplicates, prohibited phrasing and inconsistencies with source data make it into publication. This harms not only content quality, but also process control with a larger number of SKU.
A separate group of risks involves operational and legal errors. Dropping the HITL stage for strategic, regulated or complex products increases the risk of costly corrections and incorrect communication. It is also dangerous to ignore privacy rules when sending product data to the API. A lack of A/B testing additionally makes it harder to assess whether automation really improves visibility, CTR or conversion.
These errors are most effectively limited by combining template segmentation, QA rules and human verification where the stakes are high. It is worth regularly analysing rejections, because they show whether the problem lies in the data, prompts or model. If the team corrects texts manually but does not remove the source of the error, the problems return with the next batches. Automation delivers repeatable quality only when risk is managed as a process.
FAQ
Frequently asked questions
How can you tell whether an AI tool for product descriptions delivers consistent quality?
You need to check a series of outputs on a batch of products from one category, not a single example. What matters is a consistent tone, complete structure, factual accuracy and no internal duplication.
Do poor data from PIM or a feed affect product description quality?
Yes, because the model works with what it receives as input. If the data is incomplete or messy, the description usually becomes generic, imprecise or incorrect.
Which product data helps most when generating good descriptions?
The most important are attributes and technical specifications, variants, materials, composition, finish, use cases, compatibility and usage limitations. These fields can be mapped well to a template and used to build coherent content from them.
Why is data enrichment important when creating product content?
Because it turns raw parameters into information that is useful for the customer and the model. As a result, the description shows not only technical features, but also use, benefits and limitations.
How does prompt engineering affect the consistency of AI descriptions?
A well-designed prompt defines the text goal, sections, style, length and how to use the input data. Without clear instructions, the model will not set the correct structure or content priorities on its own.
When is it worth adding a human to the product description generation process?
When a product is strategic, regulated or complex, a human approval stage is mandatory. Human-in-the-loop protects against errors that automatic rules may not catch.